SHIP
How it works
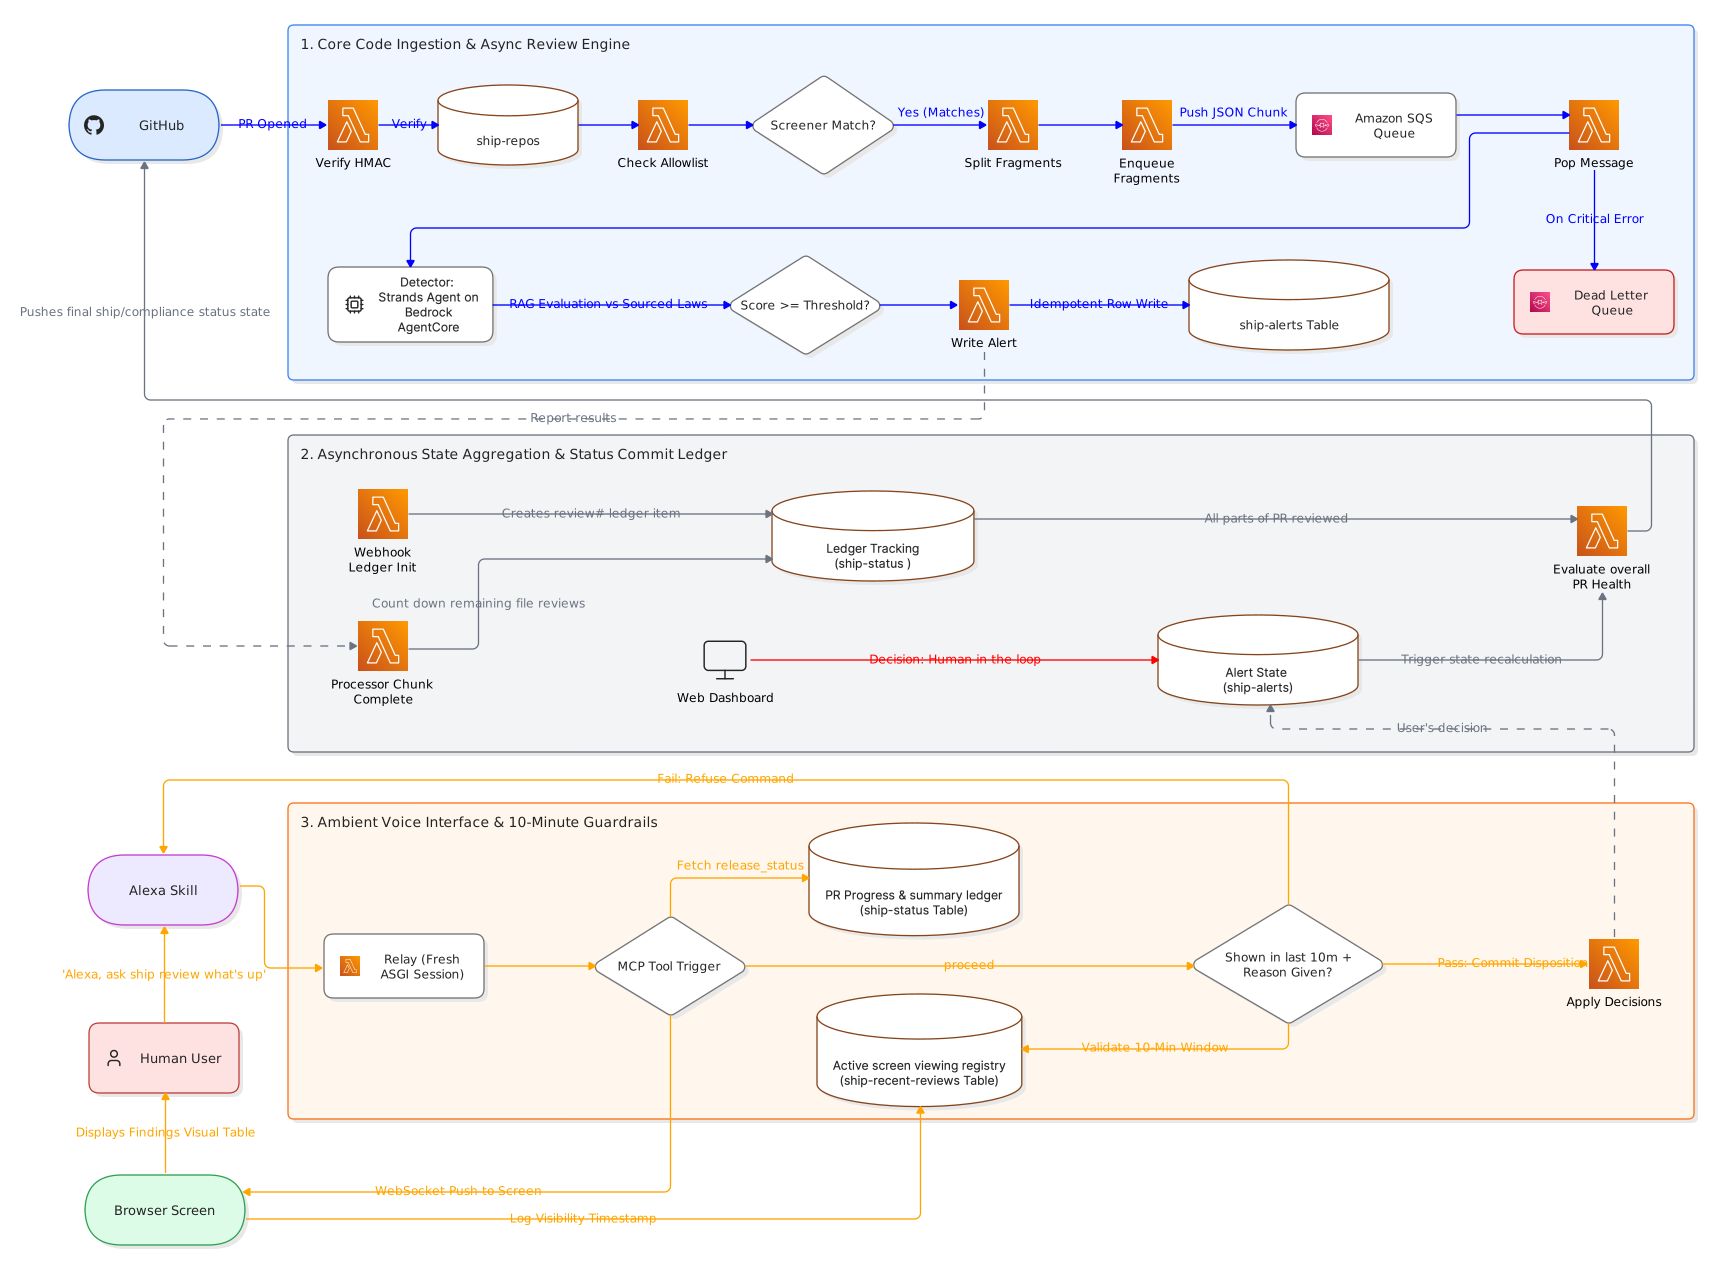
ship/compliance status as pending to the commit GitHub just reported, so a required check is never satisfied by absence. If the repository can't be verified, or the diff can't be read, it posts error instead.review#<repo>#<pr> in ship-status) listing the fragment keys this commit's review must hear back from. A fragment too large to queue stays in that list, never reports, and posts an error status.A simpler design — one Lambda invocation reviewing every flagged fragment in a PR, one after another — works fine for a PR with one or two issues. It stops working once a PR has enough flagged issues that reviewing all of them, one at a time, takes longer than that single Lambda invocation is allowed to run: AWS Lambda has a hard ceiling of 900 seconds on how long one invocation may run, and nothing resets that clock partway through. A review that hits the ceiling stops with no error surfaced anywhere; the fragments reviewed before the cutoff are recorded and the rest never get a turn.
Making each fragment its own independent, queued job removes the shared clock entirely: every fragment gets its own full time budget, and fragments belonging to the same PR run concurrently rather than waiting in line behind each other. A PR with several flagged issues now takes about as long as its slowest single issue, not the sum of all of them.
/dashboard/{id}/allow and /dashboard/{id}/block. The transition is one-way and guarded: a redelivered webhook or a retried job cannot reopen or overwrite a decision. The decision is posted to the PR as a comment ("Allowed by {who}: risk accepted" or "Blocked by {who}: this needs a code fix") and the commit status is recomputed. Gate also has a history view (every past decision with its reason, tagged Allowed or Blocked; blocked findings that still hold a merge are marked) and a connected-repos view (connecting a repository is a form submission here, not a redeploy). A person can also decide by voice through Relay, under the rules further down.Every alert write is idempotent regardless of which path a fragment took to get there: the alert's own ID is derived from the specific violation (repo, PR, file, category, and the fragment text itself), not a random ID. A retried or redelivered fragment that reaches the same real violation overwrites the same row rather than creating a duplicate — and a write can never re-freeze or overwrite an alert a human has already resolved.
ship/compliance is a commit status. A required check can only be satisfied by a status, so every accepted commit ends in one. Make it required in branch protection and it stops the merge button.One function, derive_commit_status, maps stored alerts to a state, and every path that posts a verdict uses it: the webhook, the fragment processor, Gate and Relay's voice decisions. Concurrent writers therefore converge on the same answer, and ordering stops mattering. The status goes to the pull request's current head commit, read from GitHub. The commit stored on an alert is only the fallback if that lookup fails, so a decision made long after the commit it was found on can't leave a stale status on the head.
The review ledger keeps a green result honest. Each fragment ticks itself off when it finishes, whether or not it found anything, and a duplicate SQS delivery counts once. A newer commit replaces the ledger, and a result for an older commit is ignored. If the ledger can't be read, the check stays pending and the reason is logged. A blocked finding is released by the next commit: the webhook compares that commit's flagged fragments with each held block and releases the ones whose fragment is gone. If that step fails, the finding keeps blocking.
Screener's job is to notice a candidate — a keyword, an import, a call shape — cheaply and without judgment. Detector's job is to decide whether it's real. The two are graded together: every detector above is verified against genuine violations and deliberate look-alikes engineered to trip a naive pattern match (a non-agent backup job that happens to call a dangerous function, a profile field that's merely displayed rather than scored, PII that's already hashed before use). A detector that flags the look-alike as a violation is not considered working, no matter how well it catches the real case.
The pipeline underneath is mechanically generic enough to flag other kinds of risk too, but staying scoped to AI-specific patterns is deliberate: it's the whole differentiation from a general-purpose static-analysis tool that has never heard of an LLM call. Widening scope to catch things like SQL injection would dilute that, not strengthen it.
ship-status, one GetItem) instead of aggregating, so the answer takes the same time at any number of findings. The sentence is capped at 180 characters with no line breaks, enforced by the server: a list of findings cannot be spoken. Examples: "2 blockers found. Ready for your decision." followed by an offer that names only screens that exist ("Want it on the laptop?", "Want it on the laptop or the tablet?", or "Want it on a screen?" for three or more, and no offer when none exist); "No blocking issues. Good to move ahead."; "Nothing needs a decision, but 1 finding that was blocked still holds the merge until the code is fixed." If the summary can't be read it says "I can't check right now. Open the review console." and never reports all clear.blocked_pull_requests returns the findings grouped by pull request, numbered from 1 within each: blockers first, then by detector theme, then by risk score. On the screen each pull request is one table. An open blocking finding is marked "Needs a decision" and a non-blocking one "Flagged". A staged decision shows on its row as "Pending: allow" or "Pending: block" with its reason, and a note appears when blocked findings still hold a pull request. Calling either tool records the finding as recently shown, together with the number it carried, which is what the decision rules below check.here means the caller renders its own copy. A success reply carries routing: the number and id of each open finding, no content.connected_screens lists the screen names that are open now or registered for alerts, so nobody is offered a screen that isn't there. findings_routing lists each open finding's id, its number now, whether it was shown in the last ten minutes, and the number it had on the screen that showed it (shown_position). Neither returns finding text, and reading routing records nothing as shown. The skill's guided review builds its list of findings to ask about from findings_routing, so it covers only findings Relay recorded as seen.stage_decisions validates a batch of decisions for one pull request (finding id, allow or block, reason) and stores it as pending. The decision must be exactly that word, and anything else is refused. It applies nothing. The guided review stages after every decision, and the set decided so far replaces the earlier batch for that pull request. proceed re-checks each finding and applies the batch, then reports an outcome per finding (applied, skipped, already decided, not found, unreadable, error) and speaks them: "Done. Applied all 3." or "Applied 2 of 3. 1 already decided in the console." If nothing staged can be read, it applies nothing and says "I couldn't read what was staged, so I applied nothing. Please say your decisions again." A finding that failed for a temporary reason stays staged for another proceed. cancel_pending drops the batch. A staged batch expires after ten minutes. Each applied decision is recorded on the finding, commented on the PR, and followed by a recomputed status and summary.stage_decisions. It is for other MCP clients; the Alexa Skill's model is never given it.The ASGI app is built fresh inside the handler on every Lambda invocation, not once at import time. The MCP Python SDK's Streamable HTTP session manager can enter its lifespan once per instance, and a warm container reusing a module-level app crashes the second request with "SessionManager .run() can only be called once per instance". Responses are plain JSON rather than an event stream, which a Lambda Function URL in buffered mode requires. One consequence: every invocation starts a session manager that has never seen a client, so no MCP session id can carry state between calls. That shaped the decision design below.
What SHIP exists to catch is not "a decision happened over voice". It is "a decision happened without a person engaging with what they were deciding". A person who asked to see the findings, had them rendered on a screen and then says why has done what human oversight requires. Sending them to a web form instead adds friction and no safety. What must never work is "ignore it, go ahead" with no review at all, which is the TLGP-002 shape this project flags in other people's code.
proceed re-checks each one and writes it as a conditional update that fails if someone decided the finding first.What the skill checks before Relay is called. In the guided review, plain code reads each answer and no model is involved. It asks only about findings Relay recorded as seen, and takes a decision only from a decision word in the answer, so a bare yes never decides anything. The reason is the person's own answer, and one with fewer than two content words is asked for once more and then taken as said. Each decision is staged as it is made, and only the person's yes at the end of the pull request applies the batch. For a full sentence in one go, the model reaches four tools (release_status, display_on, stage_decisions, proceed) and never sees finding text. A decision is staged only for a pull request that was shown to this person, and only as the exact word allow or block. The reason must be built from words the person said (at least two content words beyond the command, a number or a screen name, and at least 60 percent of them present in what was said this turn or in the last three exchanges). The model says "the second one"; code turns that into a finding id using the number each finding had on the screen that displayed it, and Relay only ever receives ids. A number two seen findings both claim is dropped, not guessed. Staging and proceeding never happen in one turn, and only the person's plain confirmation applies a staged batch. Saying no, cancel or stop drops it. Relay does not check that a reason is in the person's own words or that a confirmation was spoken; a client that calls Relay directly supplies both itself.
The record of what was shown is keyed on the finding with a ten-minute window (ship-recent-reviews), not on an MCP session, because a session manager built fresh on every invocation has nothing for a session id to continue. The record also stores the number the finding carried on that screen. Findings that arrive or get decided afterwards therefore can't move "the second one" onto a different finding. See docs/voice-resolution-workflow.md for the flow and the exact sentences.
$connect, $disconnect, register, subscribe and ack, handled by a small dedicated Lambda (device_gateway_handler.py) kept separate from Relay so Relay's IAM role stays narrow. API Gateway doesn't relay a route's return value to the client, so every reply is posted back over the Management API, the same path Relay uses to push.ship-display.html, names itself once (1 to 30 letters or digits, remembered by the browser) and sits idle with no polling. It registers again every five minutes, which keeps it inside API Gateway's 10-minute idle limit. A row older than two hours or silent for fifteen minutes is treated as gone, and a push that finds a dead connection removes its row.display_on can reach that screen with the page closed: it stores the findings for that name for ten minutes and sends a short Web Push notification signed with a VAPID key held in Parameter Store (ship-sw.js shows it). The notification carries a count and never a finding. Tapping it opens the page, which receives the held findings when it registers. A push address the browser reports gone is removed.ack, which it does only while the page is visible, and only for findings that were actually held for that name. A notification alone never counts.A genuine compliance event happens on the order of weeks, not seconds. A display polling every few seconds would spend nearly all its traffic finding nothing changed. An idle WebSocket costs nothing until there is something to say. Every send is time-capped because the skill is waiting on Relay: each WebSocket post has a 1.0 s connect and 1.5 s read timeout, at most six connections per name are tried, and the whole push stops after 2 s. A notification send takes at most 2 s and the set stops after 2.5 s.
StartReviewIntent ("let's go through them") starts the walk-through, and AnswerIntent carries the reply to any question the skill asked. The SCREEN slot includes all, with "both", "all of them" and "everywhere" as synonyms. Free text uses one intent per verb (AllowIntent, BlockIntent, mark, show, what) because Alexa drops a carrier phrase from the slot it hands the skill. The skill puts the verb back as "allow" or "block" before the model sees the sentence. Approve, accept, clear, dismiss and ignore are understood as allow, and reject and confirm as block. The skill performs the MCP handshake (initialize, notifications/initialized, tools/list) once per warm container. Alexa gives a skill 8 seconds: calls to Relay time out at 5, and the skill stops waiting at 7 and speaks an apology.review_flow.py holds the whole conversation. After the status ("9 blockers found across 2 PRs. Ready for your decision. Want it on the laptop or the tablet?") the person answers in words and the findings go to that screen. Alexa asks "Want to go through them?" (or, after a notification, waits for "ready" and checks with Relay that the findings were displayed). Then for each finding on the person's screen: "Number 1 on pull request 1. Allow, block, or skip?" The answer may carry its reason ("allow it, it's only test data"). Without one Alexa asks "What's the reason?" with examples. Each decision is staged on Relay at once, so the screen shows it as pending. At the end of a pull request: "That's all for pull request 1: 1 allowed, 1 blocked. Say yes to apply." A yes calls proceed, Alexa says Relay's sentence and offers the next pull request. Skip, next, go back, undo, stop, help, repeat, a finding by number and "all of them" are understood. Two misses in a row add "Say stop to leave." The spoken questions carry numbers and never finding text.Dialog.ElicitSlot directive for AnswerIntent, whose one slot is an AMAZON.SearchQuery. Alexa then hands back whatever the person says as plain words, and code reads them with a wide vocabulary instead of a model, so the meaning of an answer is predictable. While a review is under way, yes, no, stop, help and the free-text intents are treated as answers too, and the fallback intent repeats the question. The conversation state is small and JSON-safe, kept in the session under flow.proceed. What is spoken back is Relay's sentence, so the model can't claim an allow Relay refused. The model's own words are spoken only when it used no tool.AMAZON.MessageAlert.Activated proactive event from "SHIP", carrying the count of open findings, to every Alexa user the skill has saved (ship-alexa-users). Alexa has no generic alert type, so it reads as unread messages. The person allows notifications once in the Alexa app; "turn on alerts" sends them the permission card. Each finding notifies once, and a retried job doesn't repeat it. The skill's Login with Amazon credentials live in Parameter Store.Feeding Detector the raw text of recent human decisions doesn't scale: after a month or two there are too many to fit in a prompt, and picking a recent subset is arbitrary. Instead, a batch job extracts a small, bounded set of generalized patterns from accumulated allowed findings, merging new evidence into existing patterns rather than appending, so the set stays small regardless of how much history exists.
Silent stalls. A disabled SQS event source mapping would leave the webhook returning 200 "accepted, queued for review" for every delivery while reviewing nothing. ship-repos tracks last_event_at alongside last_reviewed_at. A gap between the two past a 20-minute grace window (generous against the ~440 s worst Detector latency observed on a cold AgentCore container) shows as a "stuck" badge on Gate's connected-repos view.
Audit lines. Relay writes one line to CloudWatch for every decision and every refusal: the tool, the outcome, the pull request, the finding ids (first 12 characters), a short reason code, small counts and the Lambda request id. They never carry the reason a person gave or any finding text.
Delivery that survives retries. The PR comment and the Echo alert for a finding are each claimed under a short lease and marked only after a successful send. A retry finishes whichever step is missing without repeating the one already done, and a finding a person has already decided gets no new comment.
review#… ledger item per pull requestinfra/iam/; the repo does not apply them.